

In the early afternoon, the assembly hall of a manufacturer in the automotive sector suddenly faces an unexpected issue. The gradual loss of pressure in the compressed air piping system indicates more serious problems, which escalate a few minutes later in a complete loss of pressure in the pipeline, which will prevent the use of all pneumatic tools. The production stops, and a race against time begins. Every hour costs the manufacturer a significant amount of money. This unenviable situation is caused by the air compressor failure.
Early maintenance could have prevented all this
The signals indicating this failure occurred weeks before this event. But for this part of the equipment, no tools for early failure detection were used. You might think about dozens of similar situations that could cost your business considerable financial and time expenses. What measures could have been taken to prevent this? Condition monitoring is a process of measuring the parameters of machines such as the temperature, vibrations, pressure, electric current etc. to detect and prevent failures.
Examples of parameters that can be used for condition monitoring.


Not just monitoring, but proper diagnostics
You might argue that you use a bunch of sensors to monitor your critical infrastructure. That is a good approach; but in such a large amount of data, looking for various outliers is like looking for a needle in a haystack. To overcome this problem, traditional condition monitoring must be combined with data science and machine learning.
What anomaly means
In the context of condition monitoring, we must also mention anomalies. A classic definition of an anomaly was given by Douglas Hawkins: “An anomaly is an observation which deviates so much from other observations as to arouse suspicions that it was generated by a different mechanism.”
There are a number of diagnostic approaches that can help reveal anomalies. A few of them are listed below.
1. Decision trees
A systematic approach to identifying the main cause of an event, with the use of a fault tree diagram. Needs a lot of domain expertise - Expensive to build and maintain.
2. Rule-based
Use IF/THEN statements applied to the data to distinguish between normal operation and fault state. Needs a lot of domain expertise - Expensive to build and maintain.
3. Model-based
Machine learning techniques using trained models for normal operation. In case of anomalies, the model output indicates the deviation. Needs high computing resources - Requires a good amount of historical data.
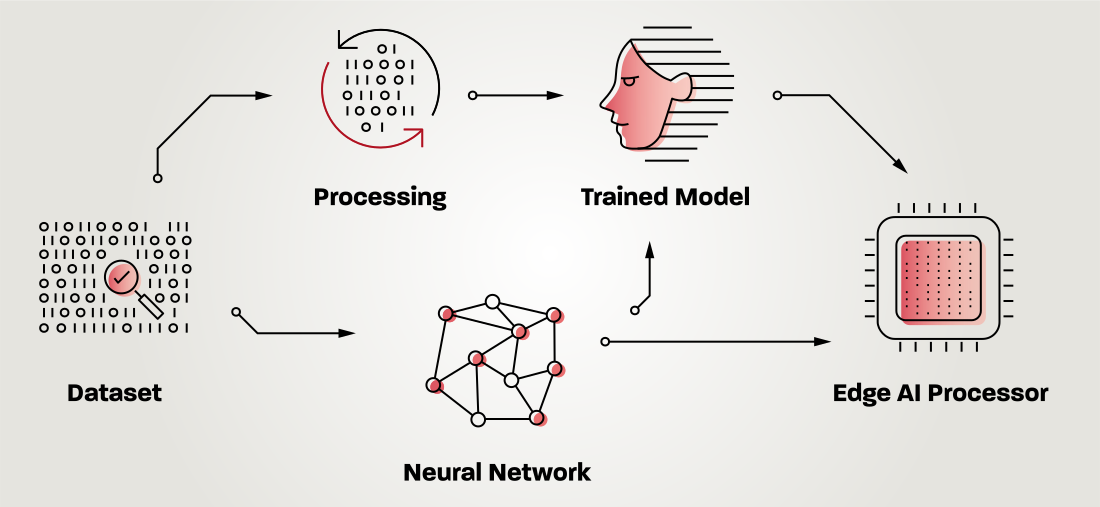
The use of machine learning techniques in anomaly detection has become quite popular in recent years.
However, not all of the known ML methods are suitable for this. In the real world, we typically miss enough data representing the fault state. For this reason, using supervised learning methods that map input to output based on many examples in the learning process is not a good choice.
A more suitable method for anomaly detection is the autoencoder.
The autoencoder, typically represented by the neural network, learns how the normal operation is represented within the input dataset. When an anomaly occurs, the autoencoder output displays a large reconstruction error.
Nowadays, condition monitoring is typically used on larger and more expensive machines.
For smaller applications, often no precautions are taken. This approach is sometimes called "run to failure." However, this does not mean that the consequences of such a failure may not be severe.
Edge computing or TinyML are examples of technologies that aim at these cases.
Edge computing is an approach where data processing takes place as close to the end device as possible – this is the opposite of cloud computing. When edge computing runs on low-power hardware (e.g. a microcontroller) and involves machine learning, we often call it TinyML.
This approach can provide several key advantages useful for smaller or remote applications.
- It can run in the offline mode
- It has a lower implementation cost
- It has low processing latency
- It provides enhanced security
Chipmakers realize that TinyML will become a fast-growing segment in the upcoming years. Therefore, many have started offering specialized AI processors supporting the energy-efficient running of ML algorithms.
To provide a more practical guide to the TinyML world, let us have a look at several examples of development boards supporting low-power ML algorithms processing:
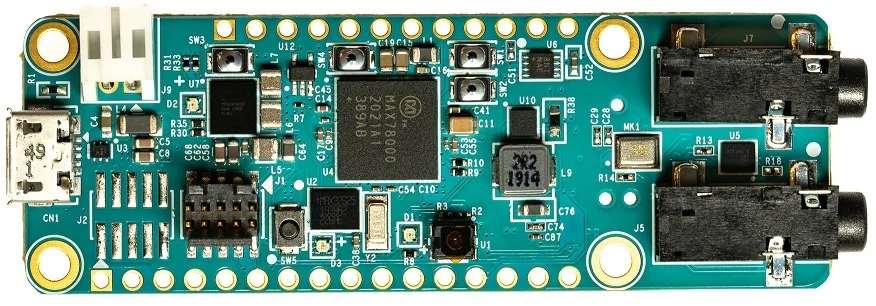
Dev. Board type: MAX78000FTHR
Manufacturer: Maxim Integrated
Chip type: MAX78000
Built-in sensors: Camera, Microphone
The MAX78000FTHR is a rapid development platform to help engineers in quick development of ultra-low-power, artificial intelligence (AI) solutions using the MAX78000 Arm Cortex-M4F processor with an integrated Convolutional Neural Network accelerator
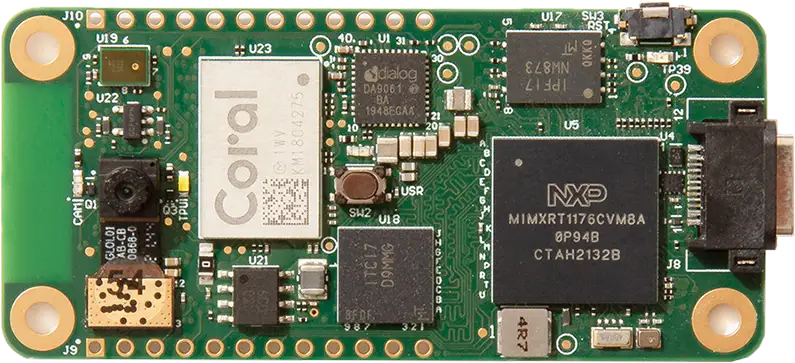
Dev. Board type: Dev Board Micro
Manufacturer: Google
Chip type: Coral Edge TPU
Built-in sensors: Camera, Microphone
The Coral Dev Board Micro is a microcontroller board with a built-in camera, microphone, and Coral Edge TPU, allowing you to quickly prototype and deploy low-power embedded systems with on-device ML inferencing
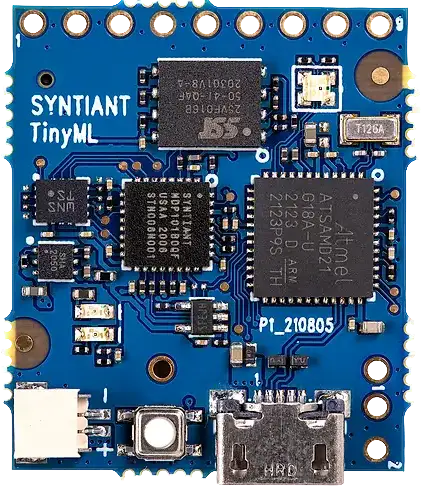
Dev. Board type: TinyML board
Manufacturer: Syntiant
Chip type: NDP100
Built-in sensors: IMU, Microphone
Syntiant’s Tiny Machine Learning (TinyML) Development Board is the ideal platform for building low-power voice, acoustic event detection (AED), and sensor ML applications
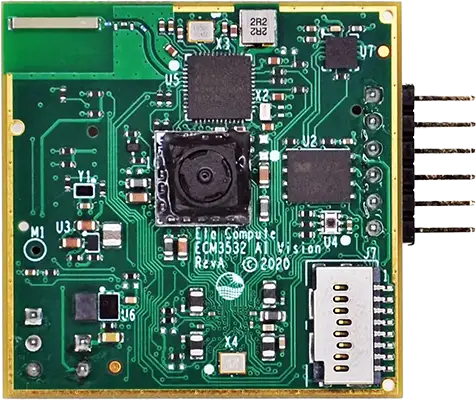
Dev. Board type: AI Sensor Board
Manufacturer: Eta Compute
Chip type: ECM3532
Built-in sensors: Camera, Microphone, light sensor
The ECM3532 AI Sensor board is an ultra-low-power AI platform with sensors that can run many algorithms: sound classification, keyword spotting, activity classification, context awareness, defect detection, and others.
Platforms listed above contain a low-power microcontroller and a hardware accelerator supporting low-power Convolutional Neural Networks inference. It can be built as an all-in-one chip (MAX78000, ECM3532) or split into a control MCU and a separate accelerator chip.
All these boards already include sensors such as a camera, microphone, or accelerometer, and of course support connection of additional external sensors.
Due to the low power consumption, it is only possible to power these boards from a battery and/or combine them with energy harvesting. We can easily build various always-on smart sensors, which will also find use in maintenance prediction. Such hardware enables easy deployment of AI and machine learning in applications where cost was a major barrier in the past. Together, with the Internet of Things, it forms one of the cornerstones of Industry 4.0.
Here at Consilia, we also deal with the AI/ML deployment in industrial, medical, and other applications. We can offer case studies, the proof of concept design, or directly support customer product development in this field. You can read more about our services in hardware and software development.
Interesting external resources
Case studies
Related Consilia projects

FPGA P4 IP Blocks
We have created parameterizable IP blocks that support various network functions used by the P4 compiler. The blocks are parameterizable and synthesizable.

Data Control and Data Acquisition PCIe Cards
By developing a new family of cards, we managed to preserve the existing running systems and enhance them with new features. Read how the development proceeded.